In October we shipped five new models on Unique AI: Claude Opus 5.5, Claude Sonnet 5.5, Claude Haiku 5.5, GPT-6.1 Sol and Gemini 4 Argon.
Before any model reaches a client, we test it inside our own agents and harnesses on the work our clients actually do: answering from internal documents and the web, RFP and DDQ answers, client-ready decks and hallucination checks. Each answer is graded against reference answers or by LLM judges built for financial institutions.
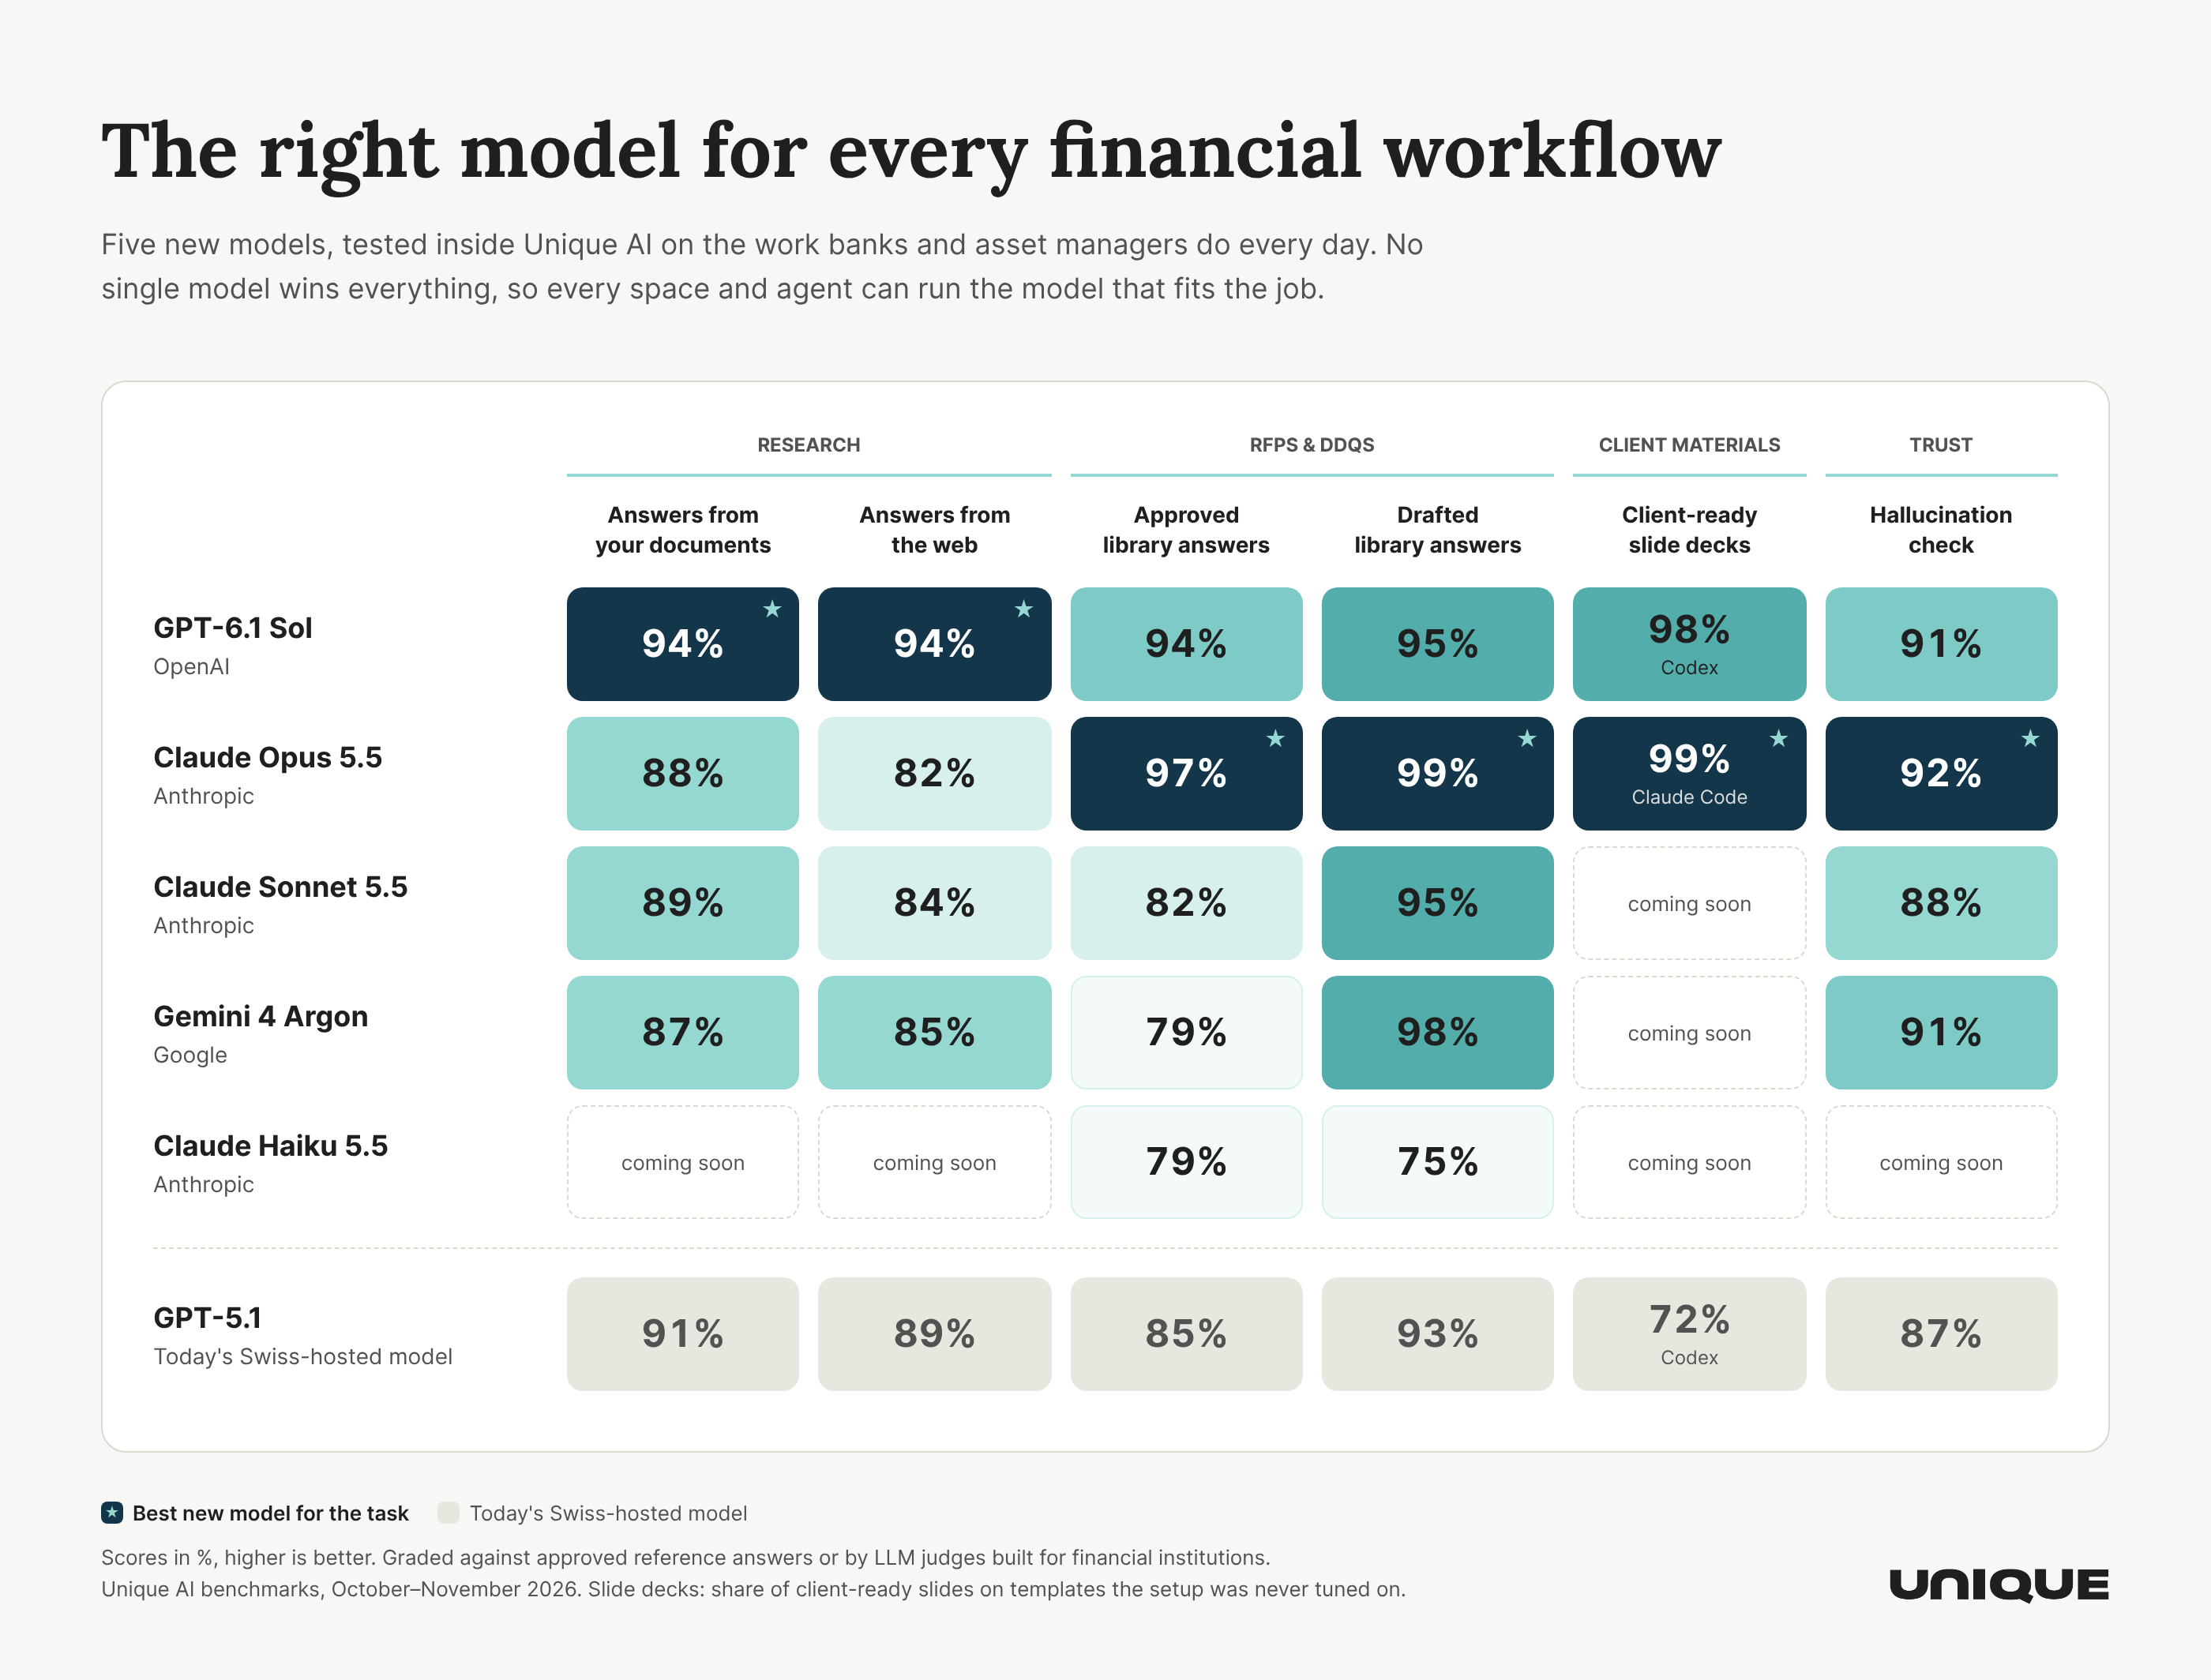
How the new models performed
GPT-6.1 Sol posts the best chat scores, Claude Opus 5.5 the best Agentic Table and deck scores, and Gemini 4 Argon comes close to the leaders on composed library answers and hallucination checks. GPT-5.1 (Swiss inference), our current production model, is shown for reference.
|
Model
|
Internal search
|
Web search
|
Verbatim library answers
|
Composed library answers
|
PowerPoint generation
|
Hallucination check
|
|
Claude Opus 5.5
|
88%
|
82%
|
97%
|
99%
|
99% (Claude Code)
|
92%
|
|
Claude Sonnet 5.5
|
89%
|
84%
|
82%
|
95%
|
–
|
88%
|
|
Claude Haiku 5.5
|
–
|
–
|
79%
|
75%
|
–
|
–
|
|
GPT-6.1 Sol
|
94%
|
94%
|
94%
|
95%
|
98% (Codex)
|
91%
|
|
Gemini 4 Argon
|
87%
|
85%
|
79%
|
98%
|
–
|
91%
|
|
GPT-5.1 (Swiss inference), reference
|
91%
|
89%
|
85%
|
93%
|
72% (Codex)
|
87%
|
Scores in %, higher is better; – = not yet tested in that benchmark. October and November 2026 runs. GPT-5.1 shown at its best tested reasoning effort.
Accuracy is closer than the headline scores suggest. On internal search, Claude Opus 5.5, Claude Sonnet 5.5 and Gemini 4 Argon match GPT-6.1 Sol on factual accuracy (about 92% vs 93%, no significant difference). On fund due diligence, the question type closest to a relationship manager's daily work, Sonnet 5.5 is the most accurate of the new models (93.0%, 2 materially wrong answers out of 69). Claude and Gemini trail overall because their answers are two to seven times longer, which the conciseness judge penalises.
Fewer wrong answers than today. With GPT-6.1 Sol about 3 in 100 internal-search answers are materially wrong, against about 8 in 100 with GPT-5.1. On web search, Sol cites the strongest sources (92.5% source quality) and, when a search returns nothing, says so instead of answering from stale training data.
What it costs
GPT-6.1 Sol delivers the best chat quality at USD 0.11–0.12 per answer, about the same as Claude Sonnet 5.5 and less than half the cost of Claude Opus 5.5.
|
Model (thinking medium)
|
Cost per answer, internal search
|
Cost per answer, web search
|
Time to first token, internal search (median)
|
|
GPT-6.1 Sol
|
USD 0.12
|
USD 0.11
|
8 s
|
|
Claude Sonnet 5.5
|
USD 0.11
|
USD 0.15
|
4 s
|
|
Claude Opus 5.5
|
USD 0.25
|
USD 0.31
|
6 s
|
|
Gemini 4 Argon
|
USD 0.40
|
USD 0.15
|
16 s
|
|
GPT-5.1 (Swiss inference), reference
|
USD 0.07
|
USD 0.07
|
9 s
|
Estimated from token counts, chat model only. Answer length drives most of the difference: Claude's and Gemini's longer answers cost more per question, and Opus 5.5 is still cheaper than Opus 5 (USD 0.37 and 0.55). GPT-5.1 remains the lowest-cost option and the one to use when client-identifying data must stay in Switzerland.
Claude Haiku 5.5 was not part of the chat runs, so no per-answer cost is reported for it yet.
Key takeaways
- GPT-6.1 Sol is the strongest all-rounder: top scores on internal and web search (94%), the shortest answers and the fewest materially wrong ones, at a mid-range cost.
- Claude Opus 5.5 is the most precise on structured work: 97% on verbatim library answers, 99% on composed answers, 99% client-ready slides with Claude Code and 92% on hallucination checks. It costs the most per chat answer among the Claude and GPT models.
- Claude Sonnet 5.5 matches Sol on factual accuracy, leads on fund due diligence and starts answering fastest (4 s), at a similar cost. Best when depth matters more than brevity.
- Claude Haiku 5.5 is the lightweight option for high-volume Agentic Table work (79% verbatim, 75% composed).
- Gemini 4 Argon is as accurate as GPT-6.1 Sol on internal documents, scores 98% on composed library answers and 91% on hallucination checks, level with GPT-6.1 Sol. Its answers are long and slower to start, so it fits drafting and verification workflows better than quick chat.
Available now
No single model wins every financial workflow, which is why Unique AI lets each space and agent run the model that fits the job. All five models are available on the platform today, and we will keep benchmarking every new model and harness on financial use cases before it reaches our clients.

Claude 5.5, GPT-6.1 Sol and Gemini 4 Argon now available on Unique AI
In October we shipped five new models on Unique AI: Claude Opus 5.5, Claude Sonnet 5.5, Claude Haiku 5.5, GPT-6.1 Sol and Gemini 4 Argon.
Before any model reaches a client, we test it inside our own agents and harnesses on the work our clients actually do: answering from internal documents and the web, RFP and DDQ answers, client-ready decks and hallucination checks. Each answer is graded against reference answers or by LLM judges built for financial institutions.
How the new models performed
GPT-6.1 Sol posts the best chat scores, Claude Opus 5.5 the best Agentic Table and deck scores, and Gemini 4 Argon comes close to the leaders on composed library answers and hallucination checks. GPT-5.1 (Swiss inference), our current production model, is shown for reference.
Model
Internal search
Web search
Verbatim library answers
Composed library answers
PowerPoint generation
Hallucination check
Claude Opus 5.5
88%
82%
97%
99%
99% (Claude Code)
92%
Claude Sonnet 5.5
89%
84%
82%
95%
–
88%
Claude Haiku 5.5
–
–
79%
75%
–
–
GPT-6.1 Sol
94%
94%
94%
95%
98% (Codex)
91%
Gemini 4 Argon
87%
85%
79%
98%
–
91%
GPT-5.1 (Swiss inference), reference
91%
89%
85%
93%
72% (Codex)
87%
Scores in %, higher is better; – = not yet tested in that benchmark. October and November 2026 runs. GPT-5.1 shown at its best tested reasoning effort.
Accuracy is closer than the headline scores suggest. On internal search, Claude Opus 5.5, Claude Sonnet 5.5 and Gemini 4 Argon match GPT-6.1 Sol on factual accuracy (about 92% vs 93%, no significant difference). On fund due diligence, the question type closest to a relationship manager's daily work, Sonnet 5.5 is the most accurate of the new models (93.0%, 2 materially wrong answers out of 69). Claude and Gemini trail overall because their answers are two to seven times longer, which the conciseness judge penalises.
Fewer wrong answers than today. With GPT-6.1 Sol about 3 in 100 internal-search answers are materially wrong, against about 8 in 100 with GPT-5.1. On web search, Sol cites the strongest sources (92.5% source quality) and, when a search returns nothing, says so instead of answering from stale training data.
What it costs
GPT-6.1 Sol delivers the best chat quality at USD 0.11–0.12 per answer, about the same as Claude Sonnet 5.5 and less than half the cost of Claude Opus 5.5.
Model (thinking medium)
Cost per answer, internal search
Cost per answer, web search
Time to first token, internal search (median)
GPT-6.1 Sol
USD 0.12
USD 0.11
8 s
Claude Sonnet 5.5
USD 0.11
USD 0.15
4 s
Claude Opus 5.5
USD 0.25
USD 0.31
6 s
Gemini 4 Argon
USD 0.40
USD 0.15
16 s
GPT-5.1 (Swiss inference), reference
USD 0.07
USD 0.07
9 s
Estimated from token counts, chat model only. Answer length drives most of the difference: Claude's and Gemini's longer answers cost more per question, and Opus 5.5 is still cheaper than Opus 5 (USD 0.37 and 0.55). GPT-5.1 remains the lowest-cost option and the one to use when client-identifying data must stay in Switzerland.
Claude Haiku 5.5 was not part of the chat runs, so no per-answer cost is reported for it yet.
Key takeaways
Available now
No single model wins every financial workflow, which is why Unique AI lets each space and agent run the model that fits the job. All five models are available on the platform today, and we will keep benchmarking every new model and harness on financial use cases before it reaches our clients.